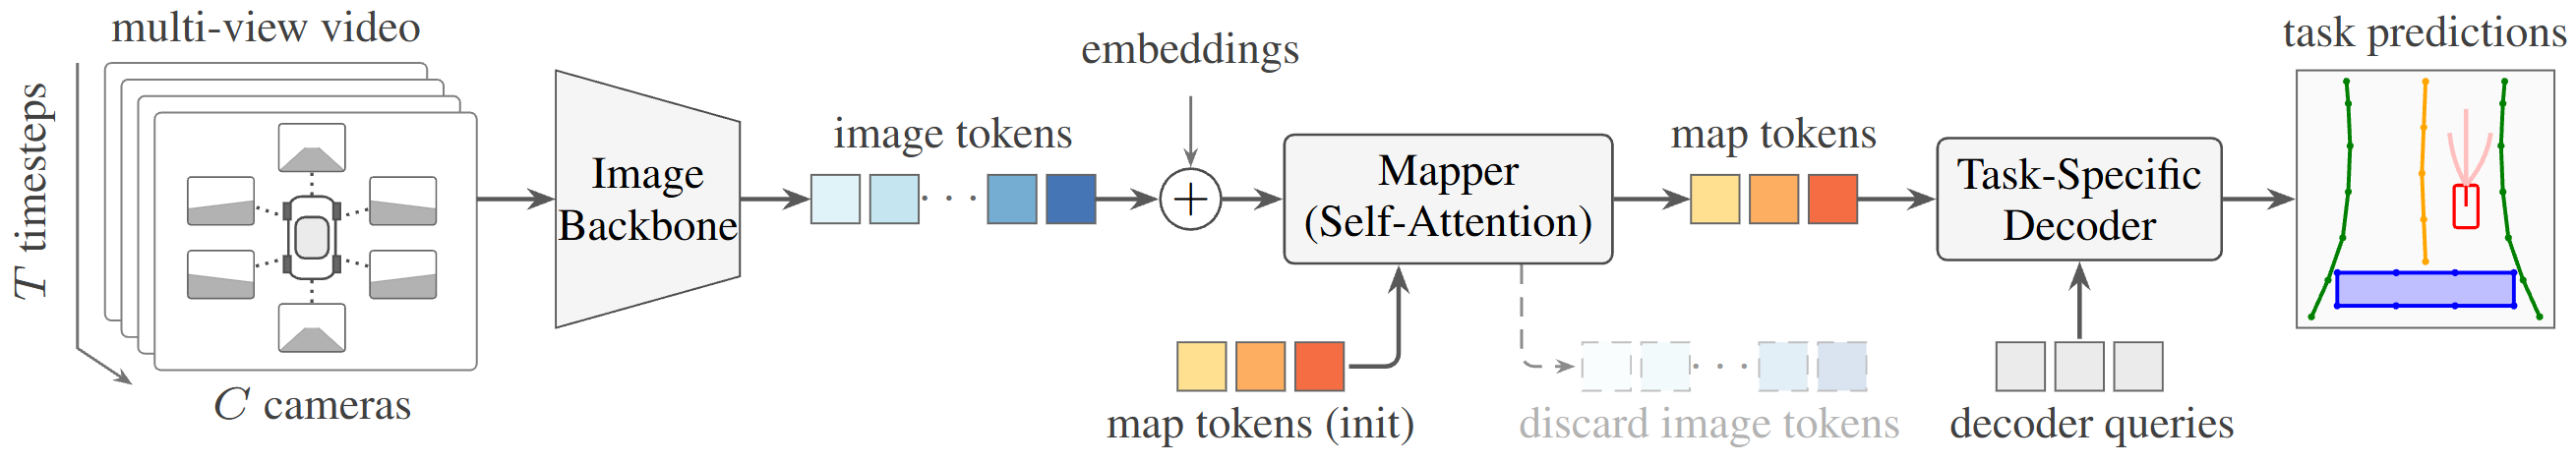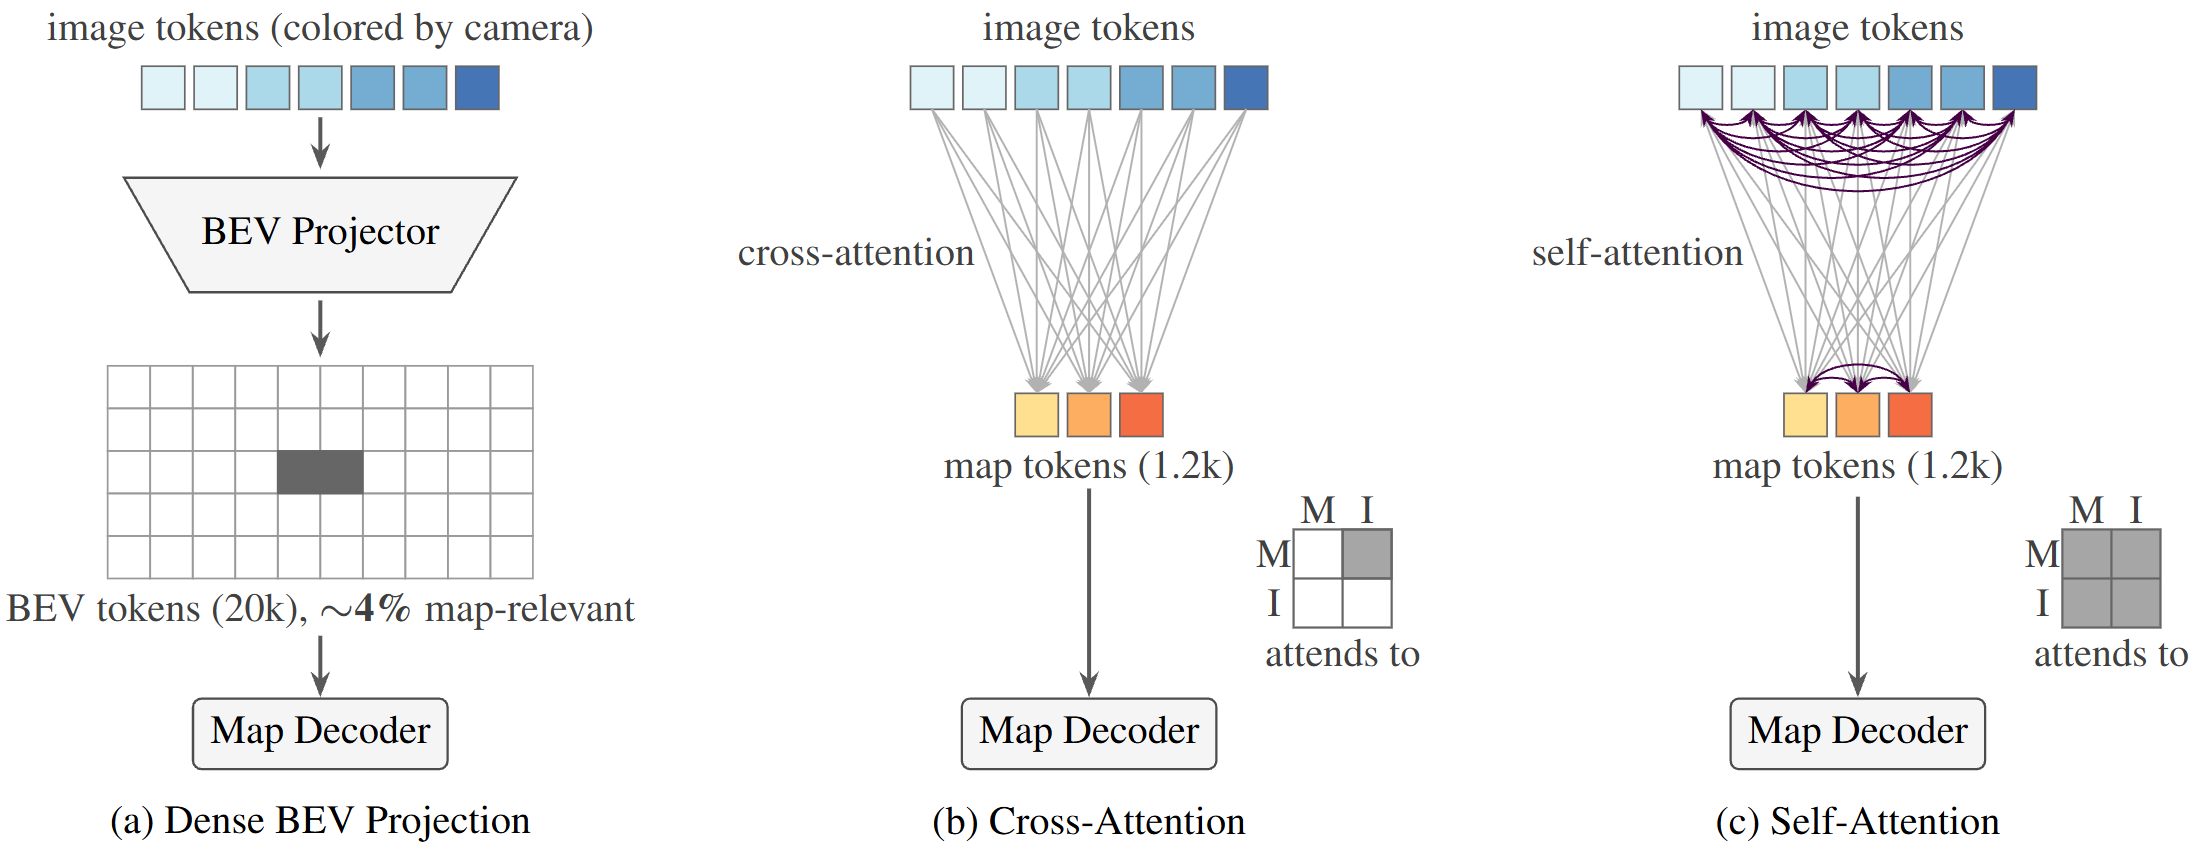
(a) BEV-based methods project image features onto a dense grid of fixed BEV cells, few of which contain map elements. (b) Vanilla cross-attention compresses image tokens into compact map tokens, with no image-to-image or map-to-map interaction. (c) Our self-attention attends to and refines all tokens jointly.